You Bought the GPUs. Who’s Tuning the OS?
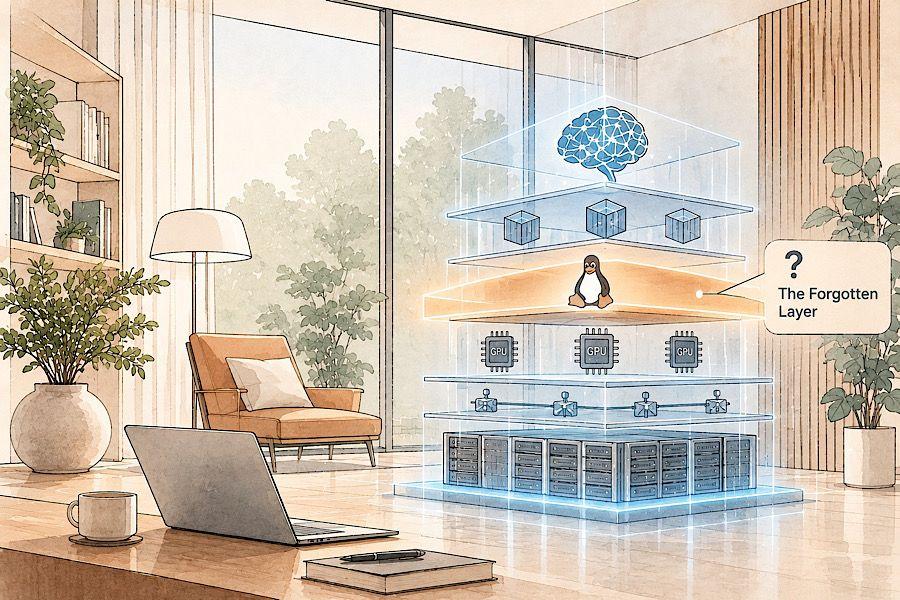
"The GPUs do the heavy lifting. Now give OS the spotlight. " Illustrated by DALL·E
Most AI infrastructure projects start the same way.
Buy high-performance servers and GPUs, install a general-purpose operating system, add GPU drivers, and assume it’s AI production ready.
It’s the age-old pattern, and too many teams still follow it. It’s time to shift that work left and treat the OS as part of GPU performance. CIQ’s session at AI Infrastructure Field Day 6 changed how I think about where AI efficiency is won or lost. It sits in a layer that rarely gets airtime.
Where the cost per token really lives
Tokens per second, time to first token and cost per token are the numbers that tie infrastructure to business outcomes. The operating system influences all three, because it decides how hardware reources is allocated and how data moves between storage, memory, CPUs and GPUs.
The currency is GPU time.
A poorly matched stack leaves expensive GPUs waiting and drags down ROI. AI is also accelerating fragmented IT, with separate stacks for labs, clouds and racks.
Homogenous Foundation to Heterogenous Use Cases
This is where CIQ comes in with RLC Pro AI, an optimised Rocky Linux for AI inference that treats the OS as an active part of GPU performance, not just the layer underneath the workload.
Think of RLC Pro AI as a baseplate.
The base is the same everywhere, and what you build on it is up to you. A single tuned image runs on bare metal and in public clouds, so the same foundation can carry a lab experiment or a production rack. Want Kubernetes? Add it. The platform is designed to fit into existing environments rather than requiring a complete infrastructure reset.
More from the GPUs you already own
The value is simple: more output from your existing hardware, with less time spent getting it to work and, most importantly, less maintenance effort.
The analytical case
- A modern kernel : Re-engineered Linux kernel that tracks newer upstream long-term releases, so GPUs and accelerator features can be supported earlier than on traditional enterprise distributions. CIQ carries the stability and tuning work, so you don’t carry the risk.
- Built in and tested as one unit : NVIDIA and AMD ROCm drivers, CUDA, NCCL, cuDNN, Fabric Manager and frameworks like PyTorch are validated together, which cuts compatibility problems and performance regressions.
- Proof points : Up to 32% more throughput on a tested image segmentation benchmark, and a setup process roughly 9x faster from clean install to first token. It also comes with CVE patching under SLAs, secure boot and FIPS readiness.
The human case
This is the part that matters over time. Teams skip the manual driver compiling and dependency troubleshooting, Operations avoid container rebuilds when host drivers are updated, controlled drift between host stack and image are controlled, and no reassembly when moving from a laptop to a fleet. Problems surface at the start, not after launch, so what worked in the lab is far more likely to work in the rack and upgrades stop being a major event.
One workflow, any cluster
A good foundation is only half the story. Fuzzball sits in the orchestration layer, on top of Kubernetes, and its promise is simple: write a workflow once and run it on-premises, in a public cloud or on a GPU cloud without rewriting it. It started in batch HPC and has grown to support both stateful and stateless AI workloads, bringing mixed fleets together.
- Portable by design: one workload file describes compute, images and storage, with a workflow catalogue offers a “run” button for common jobs.
- Resilience: checkpointing, fault-tolerant scheduling and restarts for failed jobs.
- One control plane: multi-tenancy, resource accounting, and AMD and NVIDIA GPUs together.
- CIQ’s aim is an automated stack across diverse fleets, without requiring a full “AI factory” adoption.
Trust, then verify
These are CIQ figures, so I’d check them on your own workloads.
Do the gains hold on the latest GPUs and beyond image segmentation? What was the baseline behind the 9x? What is the cost per token against a stock enterprise Linux on identical hardware and workloads? How does Fuzzball fit alongside the tools a team already runs? And how easy is it to move away later?
The part that doesn’t get the press
The OS layer rarely makes the headlines, yet much of the efficiency is untapped there. Fragmentation carries a hidden cost, because every separate stack is another set of versions to track and validate throughout its lifecycle. Security isn’t all or nothing either. With more of the operating system and control plane maintenance handled by the platform, teams can focus effort higher up the stack.
The best AI stack may not be the one with the most GPUs. It may be the one with the least friction between the hardware and the work. I’d rather spend time on AI use cases than on driver versions.
- Brian Dawson focuses on the layer nobody talks about: Build a composable AI infrastructure Stack with RLC Pro AI and CIQ and Maximizing your GPU's with a Tuned OS with CIQ
- Fuzzball aims to let workloads travel freely across clusters, clouds and GPU fleets, carrying the same workflow wherever compute happens to live: Distributed AI Workflows with Fuzzball and CIQ
- Access all sessions on Tech Field Day AI Infrastructure Field Day 6
May Mun is a guest writer for Mawaːga. You can find her on LinkedIn.