Shameback, Showback and Six Layers of Tokenomics
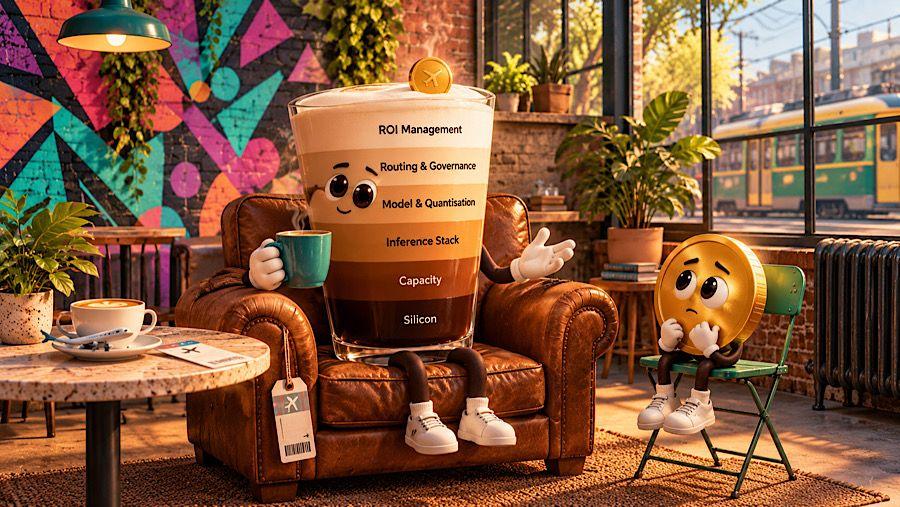
"It's not just about counting tokens," said the latte, and showed them the layers. Illustrated by DALL·E
Not everyone answers a request. Almost everyone answers an invoice.
The most persuasive anecdote in VMware by Broadcom's FinOps session at Cloud Field Day 26 featured no dashboard. It featured an invoice.
The invoice came from a large airline. Their IT team had asked the business to return idle capacity, and nobody had responded. So instead of arguing that the business needed 16 into 32, not 64 into 128, IT sent each line-of-business head a bill.
"Your team in the last month has wasted half a million dollars."
The capacity came back. The practice has a name, shameback. Shame is a crude management tool. It is also, apparently, an effective one.
The Price Comes First
Behind the anecdote sits a plainer discipline: assess, then optimise, then plan. Connect the infrastructure and a cost engine calculates total cost of ownership automatically. Cost drivers arrive preloaded, and customers overwrite them with their own discounts.
The ambition is borrowed from public cloud:
I can actually say the cost of that blueprint is going to be X dollars.
The price is on screen upfront, with month-to-date spend beside it. Private cloud has always had a cost. It has rarely had a price.
🛠️ Architectural View: From Drivers to Base Rates
Cost drivers span infrastructure (compute, network, storage), facilities (footprint, power and cooling), labour (a customisable benchmark) and licences. These roll up into base rates, the per-unit costs. A 4 vCPU machine with 100GB of storage is priced from them. Kubernetes, databases and load balancers are priced the same way.
Show It, Then Bill It
Showback tells a team what it spends. Chargeback bills it. Service providers lean on chargeback, and some enterprises do too. The rate card can be cost-plus or value-based, and granular to the second.
"The cost of running a VM is say $100, but I'm gonna charge the line of business $120."
A mirror invites reflection. A receipt invites action.
The Vanity Metric
Savings are easier to find than to bank. The lesson was learned the hard way.
"There is a huge difference between a potential savings opportunity versus actually a realised opportunity."
A dashboard may suggest deleting snapshots and pocketing the storage. Corporate policy, which requires at least three to be kept, has other ideas. The dashboard proposes; policy disposes.
That leaves the monthly tally of money "saved" as what it is: "a vanity metric", and "a feel-good factor versus trying to actually move the needle."
The number that flatters is rarely the number that matters.
🛠️ Architectural View: Costs That Move
Costs are recalculated daily. Add a host and the base rate shifts. Dynamic thresholding keeps the noise out:
"anything less than 3% or 5% don't even let me know."
The Six Layers of Tokenomics
AI makes the invoice harder to write. Run a frontier model and all you get is a token count. Run models on-premises and a whole stack sits behind that number. It has six layers across four teams, each wanting something different:
- Infra team (Silicon, Capacity): silicon sets the cost floor per token and capacity sets the effective cost. The aim is maximum utilisation of "the GPU investment that has happened."
- AI operator (Inference Stack, Model & Quantisation): a role more than an organisation. It decides which providers and models are approved, suppresses repeated work and right-sizes execution.
- App team (Routing & Governance): consumption, bounded by agent caps, quotas and circuit breakers. "There's no gain to be had by reducing the number of tokens if they have an X capacity."
- Planning & Governance team (ROI Management): the layer at the top, where value is realised.
"Are we just going to burn the dollars or is it actually going to move the needle from a business perspective?"
For a charity working with refugees, value is people reached. For others, it is profitability. The metric changes; the question does not.
The vendor is not immune. Prompts thought to run for 30 minutes ran for hours, burning tokens throughout. Even the people building the meter can be surprised by it.
🛠️ Architectural View: Observability Meets the Bill
Time to first token and time per output token sit alongside P95 observability metrics for each model. P95 is the 95th percentile, which shows the outliers an average hides. The most expensive prompts can be isolated, and agents traced through their chains: primary agent, sub-agent, tool call.
Closing Reflections
Map observability to tokens and the result is more than telemetry. It is financial literacy, and that literacy cannot stay with a specialist team:
"in the AI world, everyone needs to know how they are actually consuming tokens."
Spend is tracked against forecasts and budgets using FOCUS, the FinOps Open Cost and Usage Specification from the FinOps Foundation. Broadcom is a founding member of the Linux Foundation's Tokenomics Foundation.
The airline needed a bill to reclaim its capacity. Everyone else will need one to understand their tokens. Shame scales, provided someone writes the rate card.
🔍 Links for Further Reference
Watch the full Cloud Field Day 26 sessions: